Wagtail · 2026-10-02 · notable
One month on GLM-5.3-Flash — the Wagtail team's open-model coding test
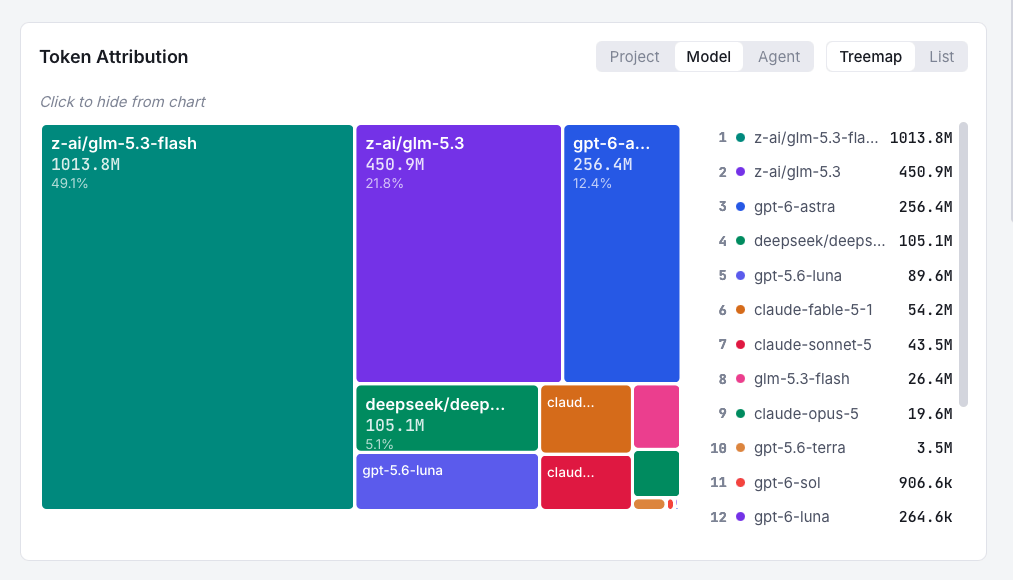
The Wagtail team tried to code all of September with GLM-5.3-Flash. Only 1B of their 2B tokens went to it, at $68. Capacity limits and one costly MCP prototype pushed the rest to other models.
A month-long attempt to do all coding work on one efficient open-weight model, with real token and cost numbers.
What is it?
Wagtail core team member Thibaud Colas reports on the team's September challenge to use only GLM-5.3-Flash for coding. The team used 2 billion tokens in total, but only about 1 billion went to GLM-5.3-Flash, at a cost of $68. Total spend came to about $218.
How does it work?
The team tracked usage per model with AgentsView. One prototype MCP server alone burned 450M tokens ($150) on a poorly chosen model, and provider capacity limits forced switches to DeepSeek V4.1 Flash and Qwen 3.8 Flash. Energy use was 35 kWh instead of the planned 10 kWh.
Why does it matter?
The report gives rare real numbers on running day-to-day coding agents on a cheap open model. Colas concludes that flash-tier models remain viable for routine development work, and recommends measuring usage locally, budgeting R&D separately, and using multi-agent setups.
Who is it for?
teams weighing open models for coding agents